Guardrails
Curated safety library, one-click enable.
Seven rules cover the most common LLM-request safety concerns: PII, credentials, prompt injection, content moderation, data exfiltration, profanity, and language gating. Configure per-rule action (block, redact, or log-only), direction (inbound, outbound, or both), and severity threshold. Custom regex block/redact patterns run alongside for org-specific needs. Manage at /dashboard/guardrails.
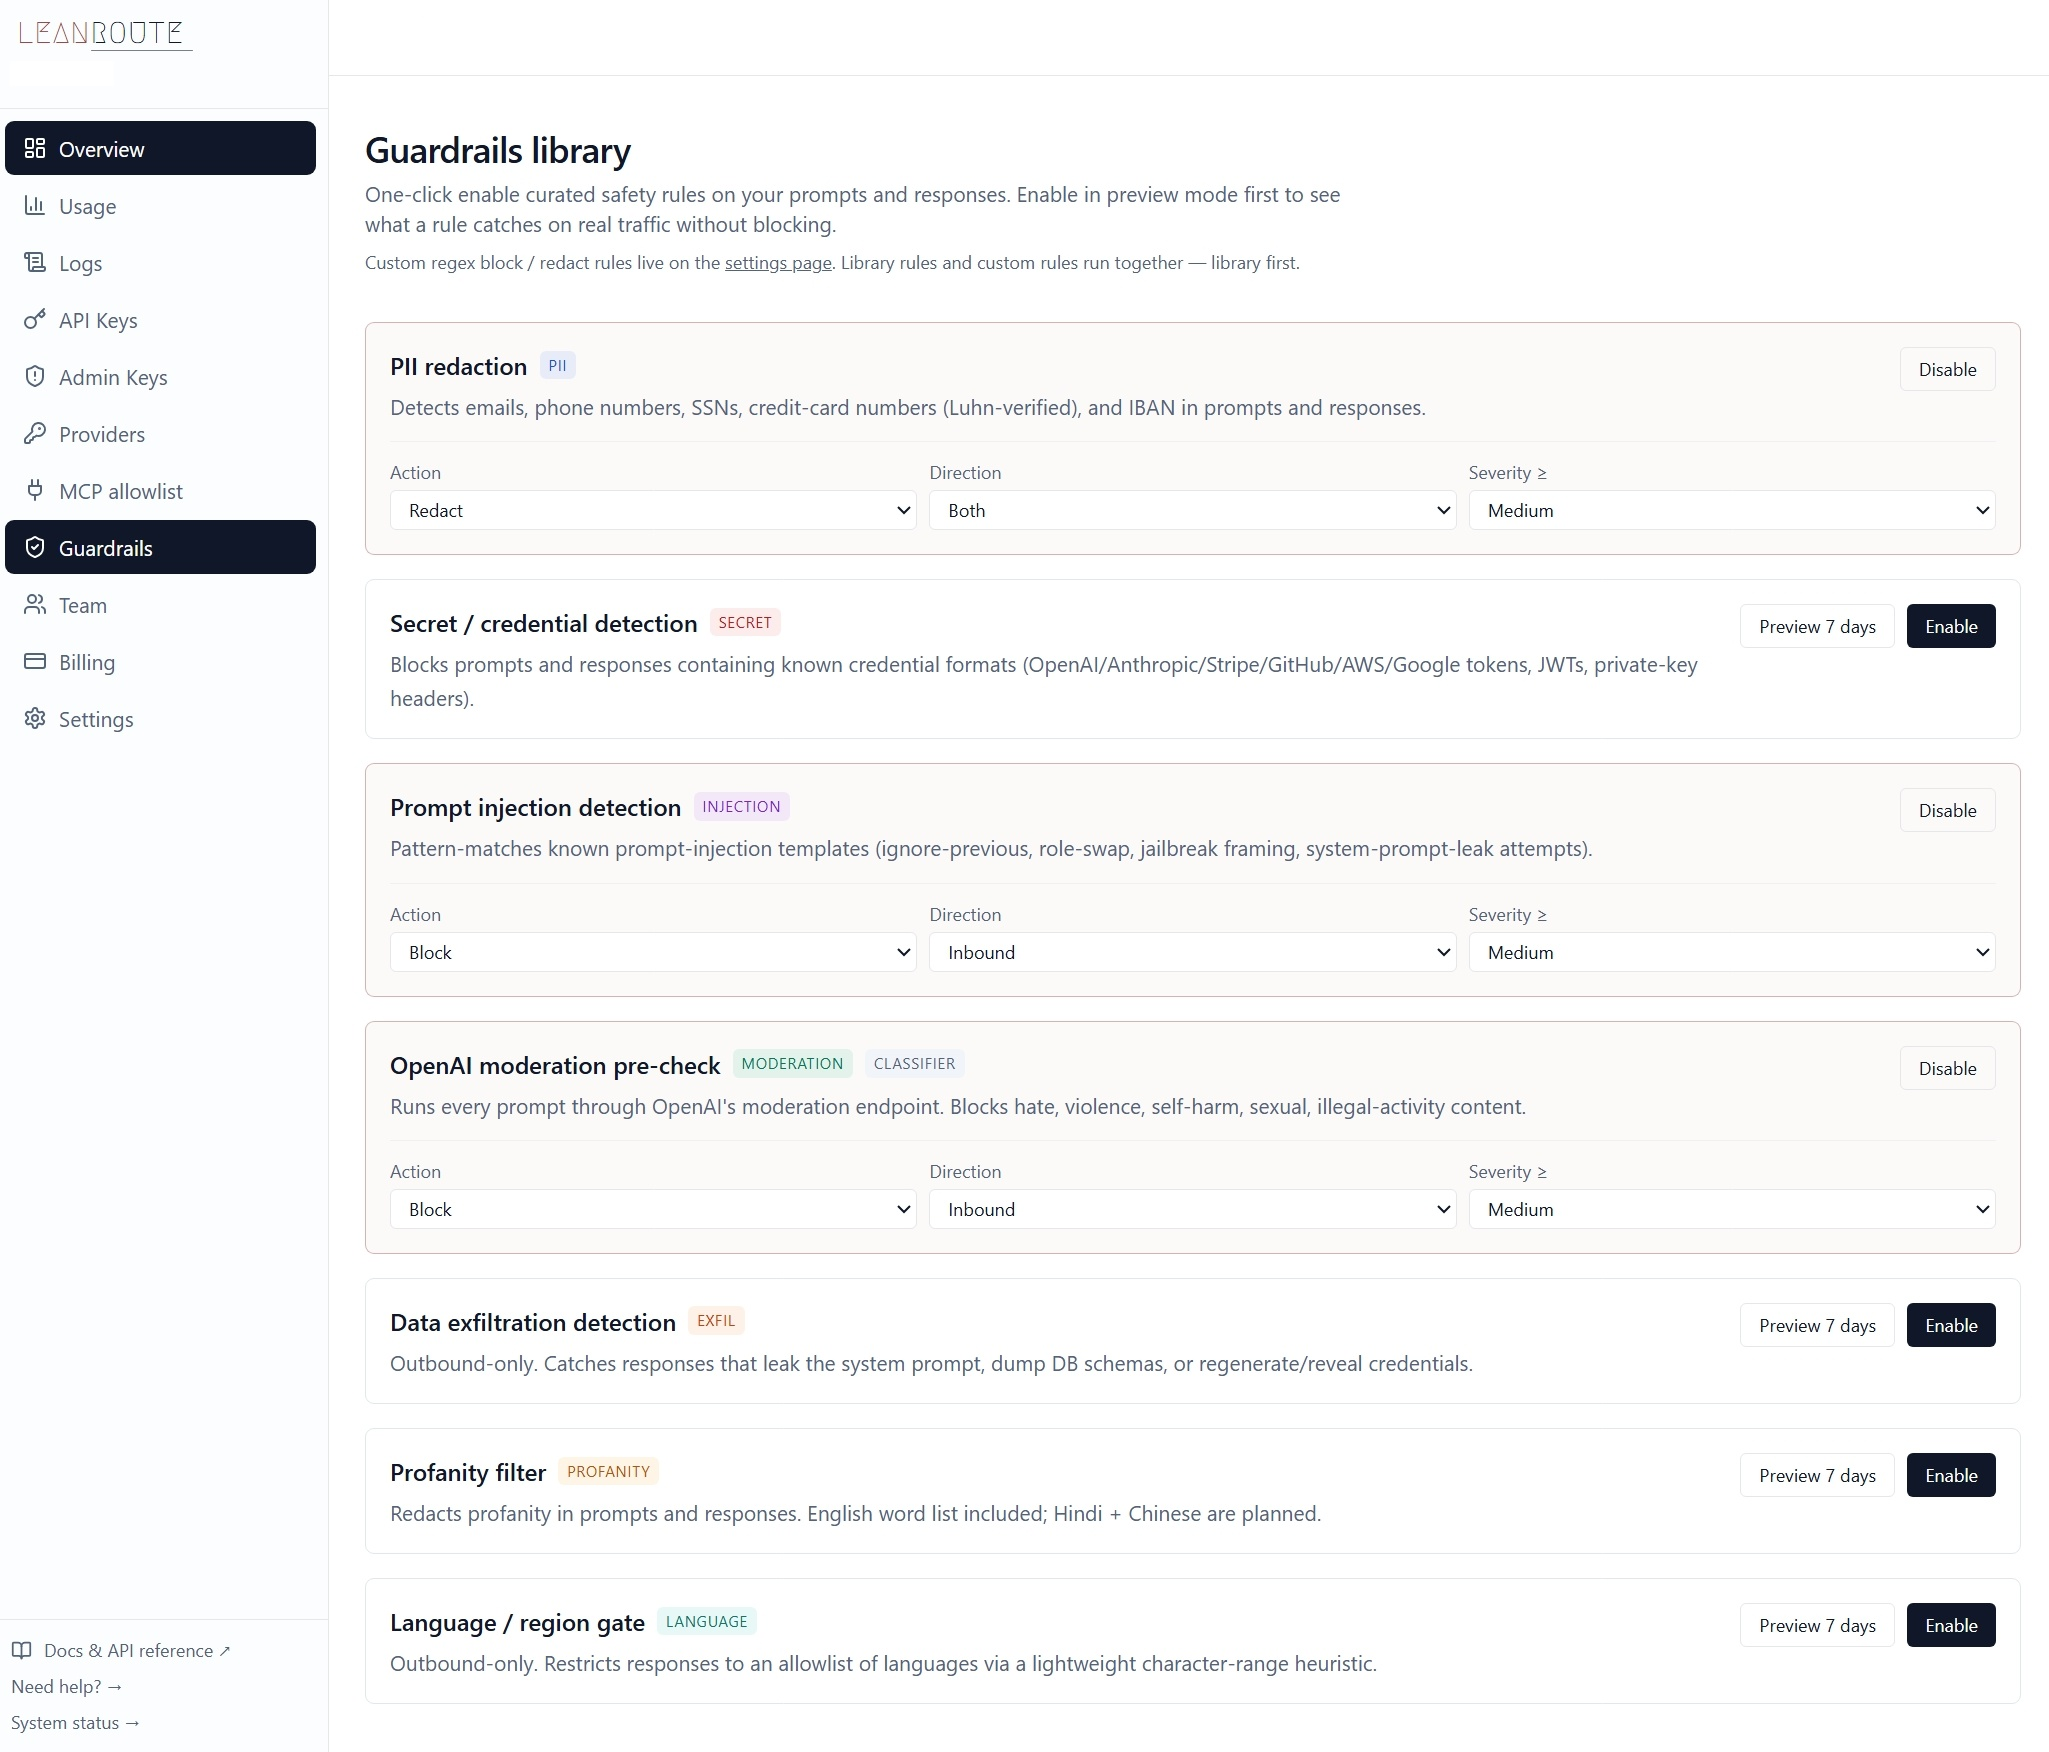
The library
PII redaction
piidefault: redact · bothEmails, phone numbers, SSNs, credit-card numbers (Luhn-verified), and IBAN. Configurable per class.
Secret / credential detection
secretdefault: block · bothOpenAI / Anthropic / Stripe / GitHub / AWS / Google tokens, JWTs, private-key headers.
Prompt injection detection
injectiondefault: block · inboundKnown templates: ignore-previous-instructions, role-swap, jailbreak framing, system-prompt-leak. Regex Phase 1; classifier upgrade planned.
OpenAI moderation pre-check
moderationdefault: block · inboundHate, violence, self-harm, sexual, illegal-activity content. Adds ~200–500ms; requires gateway's OPENAI_API_KEY env.
Data exfiltration detection
exfildefault: block · outboundOutbound only. Catches responses that leak the system prompt, dump DB schemas, or regenerate credentials.
Profanity filter
profanitydefault: redact · outboundEnglish word list included; Hindi + Chinese planned. Configurable per language.
Language / region gate
languagedefault: block · outboundRestricts responses to an allowlist of languages via lightweight character-range heuristic.
Preview mode
Enable any rule with the "Preview 7 days" button and the runtime forces the action to log_only for the window — matching requests still succeed but the response header x-gateway-guardrails-triggered fires so you can see what would have been blocked on your real traffic. When you're comfortable, flip the action to block or redact. No rule kills production on its first false positive.
How it shows up in the API
Block actions return 400 prompt_blocked with a scope + rule id so your client can show a useful error:
{
  "error": {
    "code": "prompt_blocked",
    "message": "Your prompt was flagged by the content moderation pre-check. ...",
    "scope": "library",
    "pattern": "secret-detection",
    "support_url": "mailto:[email protected]"
  }
}
Redact and log-only actions return 200 with the response header x-gateway-guardrails-triggered: rule-id,rule-id listing every rule that fired regardless of action. Full header reference at /docs/headers.
Custom regex on top
Alongside the library, orgs can add regex block or redact rules for org-specific terms (customer names, project code names, internal URLs). Library rules run first; custom regex second. Same 400/header contract. Configure at /dashboard/settings · Guardrails.
Want deeper detection?
Our library covers the common cases well. For heavier requirements — named-entity PII with model-backed accuracy, adversarial prompt-injection defense, canary-token jailbreak detection — layer a specialist in front of Leanroute:
PII detection + redaction
Microsoft Presidio
Open source, model-backed. Handles names, addresses, IDs, account numbers across many locales.
Prompt injection defense
Lakera Guard
Hosted SaaS. Detects prompt-injection attacks with a classifier trained on real attack corpora.
Jailbreak detection
Rebuff
Open source. Multi-layered including a canary-token approach to detect exfiltration attempts.
See also: Dashboard · Developer guide · Response headers · Compliance.